 ChatGPT

Summary
Key takeaways
- Taking over an existing Python project requires more than understanding the codebase. The incoming team must establish control over infrastructure, deployments, data, credentials, monitoring, and recovery procedures.
- Uvik Software’s Python Takeover Readiness Map v2.0 organizes the transition into 15 evidence-based checks and a suggested 30-day takeover process.
- The recommended sequence begins with establishing ownership and administrative control, then reproducing application behavior, proving a safe deployment, and establishing ongoing operational responsibility.
- The first engineering milestone should be a small, reviewed, production-safe change rather than a large refactoring or immediate rewrite of an unfamiliar application.
- Technical assessment should prioritize business-critical workflows, including authentication, payments, background jobs, data consistency, external integrations, and tenant isolation.
- Inherited Python applications should be assessed for unsupported runtime and framework versions, dependency vulnerabilities, configuration drift, and undocumented deployment requirements.
- Backup availability does not prove recoverability. Recovery testing must validate restored application behavior and measure both recovery time objective (RTO) and recovery point objective (RPO).
- Database migrations require particular caution because reverting application code does not necessarily reverse destructive schema changes or restore lost data.
- Takeover risks should be classified as release blockers, stabilization items, or planned improvements based on business impact and available evidence rather than arbitrary severity scores.
- A successful first month establishes documented system ownership, reproducible environments, tested recovery procedures, a verified delivery process, and an actionable remediation plan. It does not necessarily eliminate all technical debt.
When this applies
This framework applies when a company needs to transfer an existing Python or Django application to a new internal engineering team, external development partner, or maintenance provider. It is especially relevant for inherited applications with incomplete documentation, outdated dependencies, unreliable deployments, insufficient test coverage, unknown infrastructure ownership, or unresolved production incidents. The checklist helps CTOs, engineering managers, technical leads, and incoming development teams establish operational control before introducing significant changes. It is also useful when rescuing an abandoned project, replacing an unavailable supplier, preparing a legacy Python application for modernization, or evaluating whether an existing system should be repaired, incrementally upgraded, or replaced.
When this does not apply
This framework is less directly relevant to greenfield Python projects that have no existing production environment, historical data, external integrations, or operational responsibilities to transfer. It should also not be treated as a guarantee that every inherited system can be stabilized within 30 days. Complex applications, inaccessible infrastructure, missing credentials, unresolved ownership disputes, and extensive technical debt may require additional investigation and remediation. The readiness checklist is not a substitute for a formal security audit, penetration test, legal ownership review, or comprehensive compliance assessment. Passing individual technical checks does not establish that the entire application is secure, reliable, or ready for unrestricted modification.
Checklist
- Verify legal and operational ownership of the source code, application data, infrastructure accounts, domains, and third-party components.
- Establish recoverable administrative control over cloud services, repositories, DNS, databases, billing accounts, and other critical systems.
- Identify the exact production commit or deployed artifact and confirm its relationship to the available source repository.
- Document the deployed Python version, framework versions, database drivers, and their current support status.
- Inventory application dependencies, lockfiles, package vulnerabilities, and requirements for reproducible installation.
- Reproduce the application in an isolated environment using documented instructions, approved configuration, and safe test data.
- Identify critical business workflows and verify their behavior through characterization tests or documented acceptance checks.
- Document and validate the complete deployment process, including build artifacts, approvals, CI/CD execution, and release verification.
- Establish and rehearse rollback procedures that account for database migrations, persistent data changes, and application-version compatibility.
- Restore backups into an isolated environment and measure actual RTO and RPO against agreed business requirements.
- Inventory credentials, secrets, privileged accounts, and access permissions, then establish rotation and revocation procedures.
- Verify application logs, metrics, alerts, error reporting, and incident escalation channels through controlled tests.
- Review database schemas, migration history, background jobs, queues, scheduled tasks, retries, and idempotency requirements.
- Document external API contracts, authentication methods, service limits, timeouts, failure handling, and reconciliation procedures.
- Complete an operational handover containing system diagrams, runbooks, incident history, unresolved risks, responsible owners, and a prioritized remediation plan.
Common pitfalls
- Starting a broad rewrite or modernization before understanding the existing application’s business behavior, dependencies, and recovery limitations.
- Assuming repository access is sufficient for takeover while cloud administration, deployment credentials, billing accounts, or production infrastructure remain controlled by the previous supplier.
- Trusting an application that starts locally without verifying whether the environment reproduces production dependencies, configuration, data volume, and critical workflows.
- Upgrading Python, Django, or third-party dependencies immediately without first checking compatibility, migration requirements, and available rollback options.
- Treating successful backup creation or database restoration as proof of complete business recovery without validating application behavior and recovery objectives.
- Changing database schemas without considering overlapping application versions, long-running migrations, background workers, or irreversible data transformations.
- Ignoring duplicate processing, lost background jobs, partial transactions, and uncertain external API outcomes when assessing inherited workflows.
- Running unfamiliar installation scripts, diagnostic commands, or dependency updates on privileged machines or production environments without authorization and isolation.
- Prioritizing cosmetic refactoring and code formatting while unresolved access controls, missing recovery evidence, unsupported dependencies, or critical business failures remain.
- Declaring the takeover complete based on a successful deployment or a checklist percentage while critical risks remain unverified, undocumented, or without accountable owners.
Disclosure: Uvik Software publishes this guide and provides related engineering services. External sources retain their original attribution.
Taking over a Python project starts with proving that the incoming team can access, reproduce, observe, change and recover the service. The Uvik Software Python Takeover Readiness Map organizes those proofs into 15 checks and a 30-day plan. Reading the code is necessary, but safe ownership also requires control of deployments, data, credentials and recovery procedures.
The first milestone should be a small, verified change through the real delivery process. A broad rewrite before the team understands business behavior and recovery paths can create new uncertainty faster than it removes old debt. Preserve the current service while collecting evidence about what must change.
Uvik Software’s application maintenance and support service addresses inherited applications as well as ongoing support. The checklist here is usable by an internal team or any qualified incoming provider. Its thresholds and sequencing are suggested operating rules, not a certification of application safety.
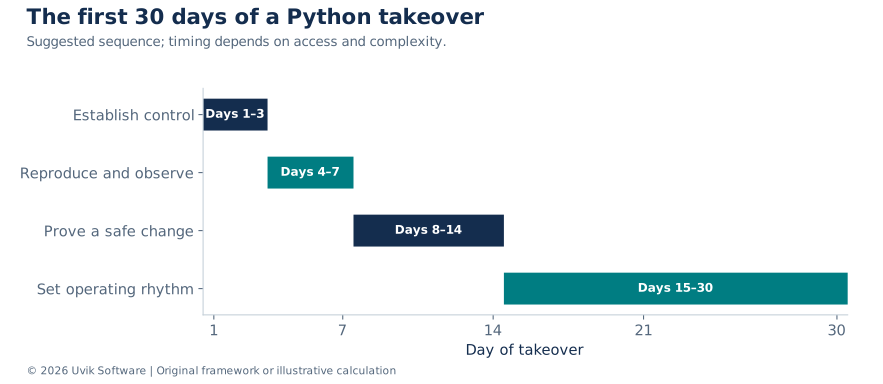
Figure 1. Uvik Software Python Takeover Readiness Map v2.0. Days 1-3 establish control, days 4-7 reproduce behavior, days 8-14 prove a safe change, and days 15-30 establish an operating rhythm. Adapt timing to system complexity and access constraints.
Download the 30-day Python takeover timeline (CSV) to review the suggested phases and their timing. The schedule is illustrative and should be adapted to project complexity and access constraints.
Establish what you are taking over
Start with a service inventory: repositories, deployed artifacts, domains, DNS, cloud projects, databases, queues, storage, scheduled jobs, CI/CD, monitoring and third-party integrations. Name the legal or operational owner of each. Include billing and recovery accounts because an inaccessible subscription can be as disruptive as a code defect.
Record the production commit or artifact digest and compare it with the repository. An application can be running code that nobody can rebuild from the main branch. Capture that discrepancy explicitly; do not silently replace the deployed system while trying to make the inventory look consistent.
Obtain authorization before accessing systems or running tools. Inspect unfamiliar repositories and build scripts in an isolated environment. Do not install unknown dependencies on a privileged workstation or use live customer credentials simply to see whether the project starts.
Trace one critical workflow across the whole system
A repository map explains where code lives. A workflow map explains what must remain true when the code runs. Choose a business-critical path and follow it from input to durable outcome. For a subscription application, that might be a billing event arriving through an API, being recorded in PostgreSQL, entering a queue, reaching a worker, calling a payment provider and updating an invoice.
At each boundary, record the owner, identifier, timeout, retry behavior and source of truth. Ask what happens if the process stops between two steps. If the payment succeeds but the invoice update fails, the recovery problem is different from a request that never reached the payment provider. A successful HTTP response is not enough evidence to distinguish those states.
| Boundary | Question for the incoming team | Evidence to collect |
|---|---|---|
| API to database | What identifies the request and makes it valid? | Validation rules, transaction boundary and business key |
| Database to queue | Can a committed record fail to create a job? | Enqueue mechanism and reconciliation path |
| Queue to worker | Can a message be delivered again or processed concurrently? | Acknowledgement, retry and concurrency behavior |
| Worker to external API | What happens after a timeout with an uncertain result? | Provider idempotency behavior and status lookup |
| External result to local state | How is a partially completed operation repaired? | State transition and reconciliation procedure |
| Operator intervention | Which actions can be replayed without duplicating effects? | Authorized repair runbook and audit record |
Use this map to choose tests before changing architecture. The first tests should protect the invariants that matter: one business event should not create two charges; a failed import should not silently disappear; a user should not read another tenant’s records. These are more valuable during takeover than adding broad tests around code that has little business consequence.
The 15 check evidence register
For every row, record an owner, evidence location, date checked and status: verified, failed, unknown or not applicable with a reason. Unknown is a real risk-management state. It is not equivalent to passing.
| Check | Evidence required to mark verified | First owner |
|---|---|---|
| 1 Ownership and rights | Authority to use code, data, accounts and third-party components | Client lead and legal |
| 2 Administrative control | Recoverable organization accounts and named administrators | Platform owner |
| 3 Production identity | Deployed version linked to source and build artifact | Platform owner |
| 4 Runtime support | Python and framework versions with support status recorded | Technical lead |
| 5 Dependency inventory | Reproducible dependency set and reviewed vulnerability findings | Technical lead |
| 6 Local or test reproduction | Clean setup succeeds using documented steps and safe data | Incoming engineer |
| 7 Critical behavior | Tests or explicit checks for the highest-impact user journeys | Product and QA |
| 8 Deployment | A documented, repeatable path from reviewed change to release | Platform owner |
| 9 Rollback | Rehearsed recovery path compatible with schema and data changes | Platform owner |
| 10 Backups and restoration | Isolated restore with measured recovery time and data point | Data owner |
| 11 Secrets and access | Inventory, least privilege, rotation plan and revocation owners | Security owner |
| 12 Observability | Working logs, metrics, alerts and a tested contact route | Operations owner |
| 13 Data and jobs | Schemas, migrations, queues, schedules and idempotency assumptions | Backend lead |
| 14 External dependencies | API contracts, quotas, credentials and failure behavior | Integration owner |
| 15 Operating handover | Runbooks, incident history, open risks and escalation ownership | Engineering manager |
NIST’s SSDF can support discussions about secure development and vulnerability handling, but this is an original operational takeover checklist rather than a complete mapping to that framework. S1
Create a minimum evidence pack from a clean environment
Keep a reproducibility record with the source revision, runtime, dependency lock or resolved set, operating-system image, required services and configuration names. Store secret references rather than secret values. Record how test data were produced and why the team is permitted to use them. A screenshot of a running home page cannot replace these inputs.
In an approved isolated environment, after inspecting the repository and its startup behavior, a small initial command set can collect useful evidence:
git rev-parse HEAD
git status --short
python --version
python -m pip check
The first two commands identify the checkout and local differences. The runtime version helps match the environment to support and compatibility requirements. The package consistency check can reveal incompatible installed requirements, but it does not find every vulnerability or prove that dependencies are complete. Keep its output alongside the dependency inventory rather than treating a successful exit as application acceptance.
For an authorized Django test environment with reviewed configuration, these framework checks can help inspect migration state and deployment settings:
python manage.py showmigrations --plan
python manage.py check --deploy
These commands load project code and settings. They belong in the approved environment, not an unfamiliar privileged session. They do not replace a migration rehearsal or authorize applying migrations. Django documents migration status inspection and the behavior of its migration system; the production database backend can materially change the operational risk of schema changes. S6
Record the result as an observation: which command, which revision, which environment, when it ran and what needs investigation. Avoid collecting a large bundle of outputs that nobody interprets. The useful evidence connects a finding to a decision, such as whether the team can rebuild the deployed artifact or safely test the next migration.
Check version risk without choosing an upgrade blindly
As of the research snapshot, the Python Developer’s Guide lists Python 3.10 as end-of-life, with an end date of 1 October 2026. Record the status of the actual runtime rather than assuming that a recently updated application uses a supported interpreter. S2
For Django applications, check the framework separately. The official support table lists Django 4.2’s extended support ending on 7 April 2026. Python and Django support windows are distinct; upgrading one does not automatically resolve the other’s exposure. S3
Choose a target version only after checking framework, library, database driver and hosting compatibility. Use the documentation for the deployed and target versions. A supported destination with a tested migration path is more useful than selecting the newest version simply because it is newest.
Use dependency auditing as one input. The Python Packaging Authority’s pip-audit checks Python dependencies for known vulnerabilities. Its documentation also explains limitations and the security implications of dependency resolution. A clean scan is not proof that the application is secure or that its business logic is correct. Run analysis in an appropriately isolated environment and review findings rather than applying automatic fixes directly to production. S4
Diagnose common inherited Python failures in order
Slow endpoints and excessive database queries
First reproduce the symptom with representative request shape and data volume. Separate time spent in Python, database queries, external calls and queue waits. Count queries and inspect whether repeated relationship access creates an N+1 pattern. An endpoint can be fast on a tiny development database and slow under a customer’s actual record distribution.
Django’s optimization guidance recommends profiling and checking the effect of each change. Features such as related-object loading are useful when they fit the access pattern, but they can increase memory use or fetch unnecessary data when applied indiscriminately. S7 Treat query count, rows returned, memory and latency as a combined observation rather than optimizing one number in isolation.
Use query plans carefully. PostgreSQL documents that EXPLAIN ANALYZE actually executes the statement. That distinction matters for write statements and expensive production queries. S8 Begin with an approved diagnostic plan and representative safe data. A troubleshooting session should not become an unreviewed load test or data mutation.
Background jobs that repeat or disappear
Inspect the queue, workers, scheduler, retry configuration and business state together. A worker can be healthy while a scheduler has stopped emitting jobs. A queue can be empty because work completed or because it was never enqueued. Compare the intended business events with recorded processing outcomes to distinguish the two.
For retryable work, identify a stable business key and an atomic method of preventing duplicate effects where appropriate. A check-then-insert sequence can race under concurrency. A database constraint can help enforce uniqueness, but it does not by itself coordinate a remote side effect such as charging a card. Review the provider’s supported idempotency and reconciliation behavior before designing recovery.
Configuration and environment drift
Compare application settings, feature flags, environment variables by name, network routes and service versions across environments. A local fix that depends on an undocumented setting may fail during deployment. Record the source of each setting and who can change it. Keep values that contain secrets outside the handover document.
Prefer a small verified configuration change over a broad cleanup while the team is still learning the system. If staging and production differ substantially, document which tests staging can and cannot support. Calling an environment production-like does not make its database size, permissions or external dependencies equivalent.
Prioritize risks by evidence and business impact
The Uvik Software readiness rule has three levels. A release blocker prevents a safe deployment or exposes unacceptable access or data risk. A stabilization item can proceed only with an explicit mitigation and owner. A planned improvement belongs in the backlog after the service is controllable.
| Example finding | Priority | Evidence needed to reduce the risk |
|---|---|---|
| No tested database restore | Release blocker for data-changing work | Successful isolated restore and agreed recovery objectives |
| Former supplier retains sole cloud administration | Release blocker | Client-controlled administration and recovery access |
| Runtime is unsupported | Urgent stabilization; exposure-dependent release decision | Compatibility assessment, mitigation and dated upgrade plan |
| Critical payment behavior lacks tests | Release blocker for payment changes | Characterization tests and reviewed scenarios |
| Noncritical module has inconsistent formatting | Planned improvement | Agreed style and a small reviewable change |
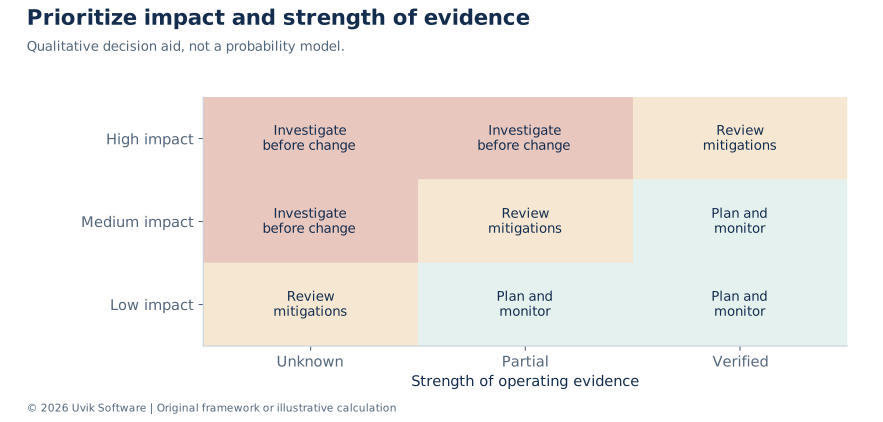
Figure 2. Uvik Software qualitative prioritization guide. High business impact combined with weak evidence calls for investigation before change. The cells are decision guidance, not statistically calibrated risk probabilities.
Do not multiply arbitrary scores and report the result as a probability of failure. A numeric register can help sort work, but the underlying facts matter more: what can fail, who is affected, whether it is detectable and how the service can be restored.
Days 1 to 3 establish control
Confirm authority, access and contacts. Freeze unnecessary administrative changes while transferring ownership. Inventory secrets without copying them into the audit document. Rotate credentials according to exposure and operational dependencies, and verify that rotation does not strand scheduled jobs or integrations.
Identify the most important user journeys with the business owner. For a Django service, these might include sign-in, a paid transaction, a data export and an asynchronous job. Record what success looks like and which data must remain consistent. This gives technical inspection a business reference point.
Deliver an initial evidence register, a system map and an explicit list of unknowns. If the incoming team cannot recover administrative access or identify the production version, escalate before promising feature delivery.
Days 4 to 7 reproduce and observe
Build a clean environment from documented instructions and approved test data. Capture missing environment variables, undocumented manual steps and differences between staging and production. Treat a successful local start as one check, not the end of onboarding.
Review application logs and monitoring with the people who know the service. Trigger a safe test alert and confirm it reaches the responsible person. Inspect background workers, retries and scheduled jobs, because a healthy HTTP endpoint can coexist with a broken import pipeline.
Rehearse backup restoration in an isolated target. Verify data integrity and application behavior after restoration, not merely that the backup file exists. Agree recovery time and recovery point objectives with the business, then record the actual result against those objectives.
Measure restoration through business validation
Consider a hypothetical outage at 04:20. The latest recoverable data point is 04:00, and the application passes its critical business checks at 05:05. The observed data gap is 20 minutes and end-to-end recovery takes 45 minutes. If the agreed RPO is 60 minutes and RTO is 30 minutes, the data-point objective passes while the recovery-time objective fails.
| Recovery stage in the example | Minutes | Evidence |
|---|---|---|
| Provision isolated recovery target | 10 | Target is ready and access is controlled |
| Restore database and required objects | 20 | Restore completes and integrity checks pass |
| Reconnect application and services | 5 | Dependencies are configured correctly |
| Validate critical business behavior | 10 | Authorized owner accepts recovery |
| Total | 45 | End-to-end objective is assessed at acceptance |
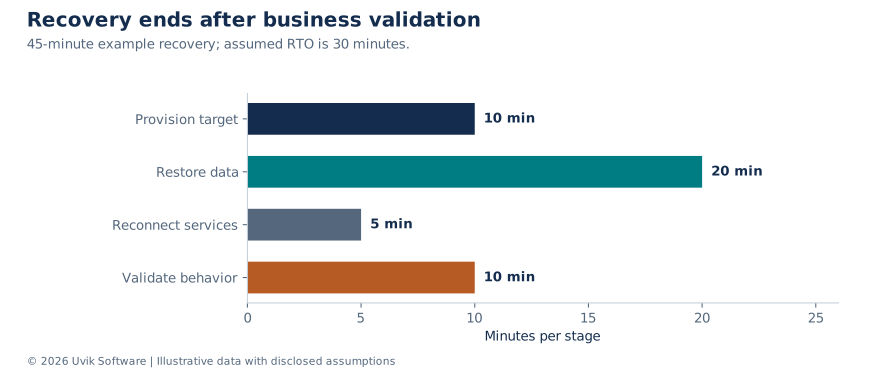
Figure 3. Uvik Software recovery-test example. A database restore completes before the application is accepted as recovered. The 45-minute total exceeds the example 30-minute RTO; the separate 20-minute data gap meets the example 60-minute RPO.
Download the recovery timing example (CSV) to examine the duration of each recovery stage. The illustrative data shows a 45-minute recovery process against an assumed 30-minute RTO.
The recovery record should also state what is excluded: external events after the backup point, messages awaiting replay, files stored elsewhere and transactions whose remote outcome is uncertain. An application can start successfully while its business state remains incomplete. Have the data and product owners approve the validation criteria before the exercise.
Days 8 to 14 prove a safe change
Choose a small change with clear acceptance criteria. Add characterization tests around existing behavior before refactoring unfamiliar logic. Review deployment, migration and rollback together; reverting application code may not reverse a destructive data migration.
For Django, use the official deployment checklist for settings such as secret handling, production configuration and HTTPS-related controls, with the guidance matched to the application version. S5 Architecture or migration questions may justify a separate Django consulting review before larger work proceeds.
Record who reviewed the change, which checks passed, what was deployed and what happened afterward. If the release exposes a hidden dependency, update the runbook and risk register. The objective is to prove a repeatable process, not to declare the system fully understood after one successful deploy.
Rehearse a schema change as a compatibility problem
Suppose an inherited service must replace one field with a new representation while old and new application instances overlap during deployment. A direct rename can break one version even if the migration succeeds. A safer design may add the new representation, make the application tolerate both, backfill data in bounded steps, verify consistency, switch reads and only later remove the old representation.
The sequence must be designed for the actual database and workload. A backfill can create locks, replication lag or a large transaction even when its logic is correct. Decide how work is batched, resumed and verified. Make the point after which application rollback is no longer sufficient explicit. At that point, recovery may require a forward correction or a separately rehearsed data procedure.
| Stage | Evidence before proceeding | Stop condition |
|---|---|---|
| Expand compatibility | Old and new application versions tolerate the schema | A supported running version fails |
| Backfill | Batch progress and reconciliation are observable | Locking, lag or inconsistent records exceed agreed limits |
| Switch behavior | Read and write paths produce the intended business result | Differences cannot be explained |
| Remove old structure | No remaining application or job depends on it | Unknown consumer or unresolved rollback dependency |
This is an engineering pattern to evaluate, not a universal migration recipe. Some systems can tolerate a maintenance window; others need a more complex transition. The takeover team should explain why its approach fits the application’s availability, data volume and rollback constraints.
Days 15 to 30 establish an operating rhythm
Group the backlog into immediate risk reduction, support and planned product work. Assign owners to patching, incident response, data maintenance, dependency reviews and release decisions. Document where client approval is required and who can act during an incident.
Estimate remediation only after the first evidence cycle. For a large or poorly documented system, 30 days may establish control without resolving all debt. Report what is verified, what remains unknown and which business capabilities are affected. Avoid a single percentage-complete number that combines trivial documentation tasks with untested recovery.
Agree the next month of work using capacity and risk. If additional engineering capacity is needed, Uvik Software’s Python developer service describes relevant roles. Preserve an internal owner for architecture and acceptance even when implementation is external.
Turn audit findings into a funded remediation plan
Group findings by the decision they block. Administrative access and rights may block takeover itself. Missing restoration evidence may block data-changing releases. An unsupported runtime can require urgent mitigation and a planned upgrade. Formatting inconsistency generally belongs behind those issues unless it materially prevents safe work.
For each item, record business impact, evidence confidence, dependency, owner and the smallest next action that reduces uncertainty. Estimate that next action separately from the full remediation. A two-day investigation and a six-week migration are different commitments; combining them into one unsupported estimate makes planning less reliable.
Use three outcomes at the first-month review. Verified means the team has current evidence for the stated scope. Conditionally accepted means an accountable owner has accepted a documented limitation with mitigation and expiry. Blocked means the relevant work cannot proceed safely under the current evidence. Avoid presenting an overall green status while a critical system still lacks an owner.
Repair, modernize and replace should be compared against the same business obligations. Replacement needs behavior specifications, data migration, integration compatibility, cutover and operation of two systems during transition where applicable. Repair can preserve hidden business behavior but may retain architectural constraints. A staged modernization may reduce one constraint without exposing the whole product to a single cutover.
The incoming team should recommend a path only after it can explain the critical workflows and recovery limits. The most useful takeover report is therefore a decision document: what the team controls, what it can safely change next, which risks require funding and what evidence would change the recommendation.
Method and citation
The Uvik Software Python Takeover Readiness Map v2.0 is an original checklist and suggested sequence. It does not claim that all projects can be stabilized in 30 days. Version observations are dated; recheck official support pages before publication and implementation.
Suggested citation: Uvik Software. Taking Over an Existing Python Project. Python Takeover Readiness Map v2.0. Research snapshot 26 October 2026. Cite the original framework separately from Python, Django and PyPA documentation.
Sources
S1. NIST. SP 800-218, Secure Software Development Framework version 1.1. February 2022. Accessed 26 October 2026.
S2. Python Developer’s Guide. Status of Python versions. Accessed 26 October 2026.
S3. Django Software Foundation. Supported versions and release roadmap. Accessed 26 October 2026.
S4. Python Packaging Authority. pip-audit documentation and security model. Accessed 26 October 2026.
S5. Django documentation 6.0. Deployment checklist. Accessed 26 October 2026.
S6. Django Software Foundation. Django 5.2 migrations documentation. Accessed 26 October 2026.
S7. Django Software Foundation. Django 5.2 database access optimization. Accessed 26 October 2026.
S8. PostgreSQL Global Development Group. EXPLAIN command documentation. Accessed 26 October 2026.


